BLOGS
Insights from ExpertsCloud on software development, AI, cloud, and building products that deliver real business value.
Ideas, Insights, and Delivery Lessons
OUR BLOGS
 Waqas Ajaz
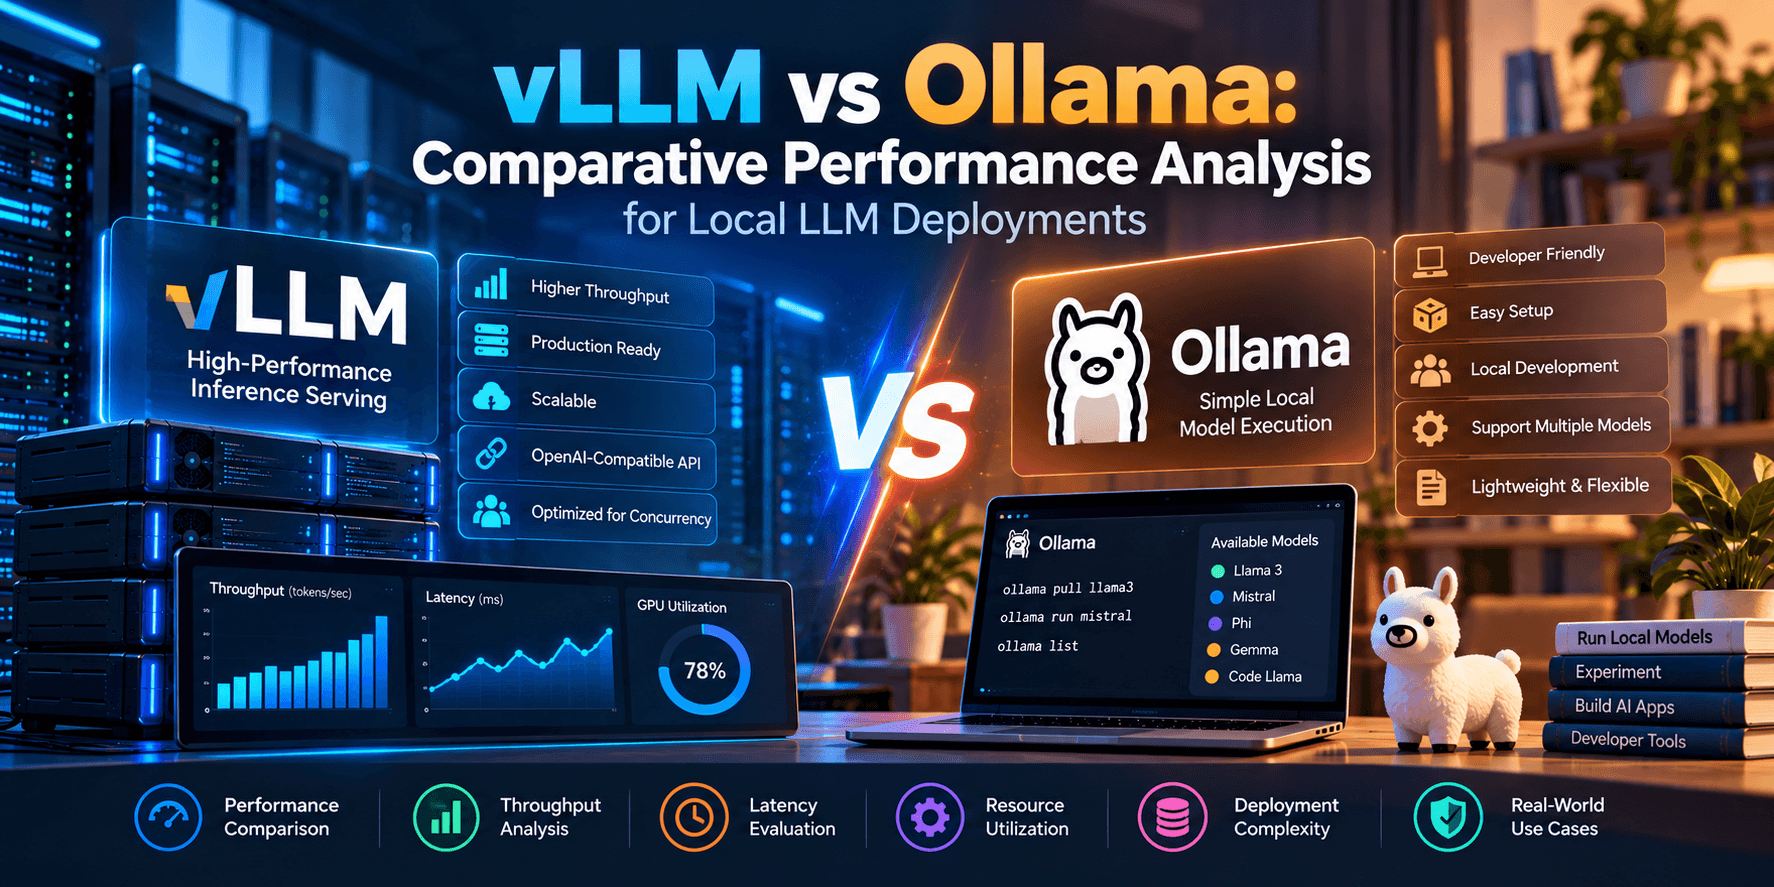
vLLM vs Ollama: Comparative Performance Analysis for Local LLM Deployments
Compare vLLM and Ollama for local LLM deployments, focusing on inference performance, throughput, latency, resource utilization, scalability, deployment complexity, and practical AI workloads.
 Tariq Sajid
Local LLM Deployment 2026: Throughput Barriers
Explore the key challenges of local LLM deployment in 2026, including throughput limitations, hardware requirements, inference performance, scalability, latency, and strategies for building efficient AI infrastructure.
 Hassan Siddique
vLLM vs Ollama: Local LLM Efficiency in 2026
A practical 2026 guide to evaluating local LLM efficiency with vLLM and Ollama, comparing performance, deployment, scalability, hardware requirements, privacy, and the right use cases for each approach.
 Nadir Hussain
Local LLM Strategies 2026: Throughput & Privacy
Local LLM strategies for 2026, covering AI model throughput, privacy, infrastructure, deployment options, and how businesses can run powerful language models locally.